
Change the document indexing model#
This guide explains how to change the model that creates vectors for document search. Changing the model or vector dimension removes old vectors and recalculates them from saved text chunks. Recognized text remains; files without saved chunks are read again. Content search may be unavailable during the switch, and results may be incomplete until file processing finishes. It is necessary to schedule the change for a suitable time.
Before you start#
- Assigning the default model requires
ai_models:read,ai_models:update,api:read,api:updateanddocuments:read. Changing parameters in Documents requiresdocuments:update. Creating a model or instance additionally requiresai_models:create. - It is necessary to find the new model's actual vector dimension. It is necessary to enter the number it returns: an integer from 32 to 2000. When upgrading from 2.5.0 to 2.5.1, prepare the 384 and 1024 indexes. If your current version is earlier than 2.5.0, agree the upgrade path with support first. For any other dimension, an administrator must prepare the search index first.
- The model must support Indexing and have exactly one active instance. Several instances of one model can return incompatible vectors.
- Do not change the address or path of the current indexing model's active instance to point it to another vector source: the system rejects that change. It is necessary to create a separate model and instance, then assign the new model as the indexing default in its card.
- API-only chunks receive new vectors from their saved text. If you also change chunk size or overlap, save these chunks outside the system first: they cannot be split again without a source file.
Example: BGE-M3 with vLLM#
On a GPU server, start a separate vLLM instance for the indexing model. This example uses vLLM 0.27.1 and BAAI/bge-m3 (vLLM must be installed and the model files available):
vllm serve BAAI/bge-m3 --runner pooling --pooler-config.task embed \
  --hf-overrides '{"architectures":["BgeM3EmbeddingModel"]}' \
  --host 0.0.0.0 --port 8001
On the vLLM server, check that the model returns 1024 numbers per vector (jq is required):
curl -fsS http://127.0.0.1:8001/v1/embeddings \
  -H 'Content-Type: application/json' \
  -d '{"model":"BAAI/bge-m3","input":["test"]}' \
  | jq '.data[0].embedding | length'
On Models, create a model with Indexing support and one active local instance. Set its model path to BAAI/bge-m3, port to 8001, and use a vLLM address reachable from the Sherpa AI Server container. For vLLM on another server, use its network name or IP. Inside the Sherpa container, 127.0.0.1 refers to that container. Leave the additional API path empty.
Configure the embeddings API format before assigning the default. The "Embeddings API format" field is available for local instances of models with Indexing support. Updating an existing instance requires ai_models:update.
- On the Models screen, select the required model and open its local instance for editing.
- In “Embeddings API format”, select “OpenAI (/v1/embeddings)” and click “OK”.
- Reopen the instance and verify that the selected format was saved. Further edits retain this format and additional connection parameters.
“Automatic (by instance type)” keeps the previous API selection based on the instance type. “vLLM (/v2/embed)” and “API v2 (/v2/embed)” use /v2/embed. “Cohere (/v2/embed, input_type)” also sends input_type. BGE-M3 in this example requires OpenAI.
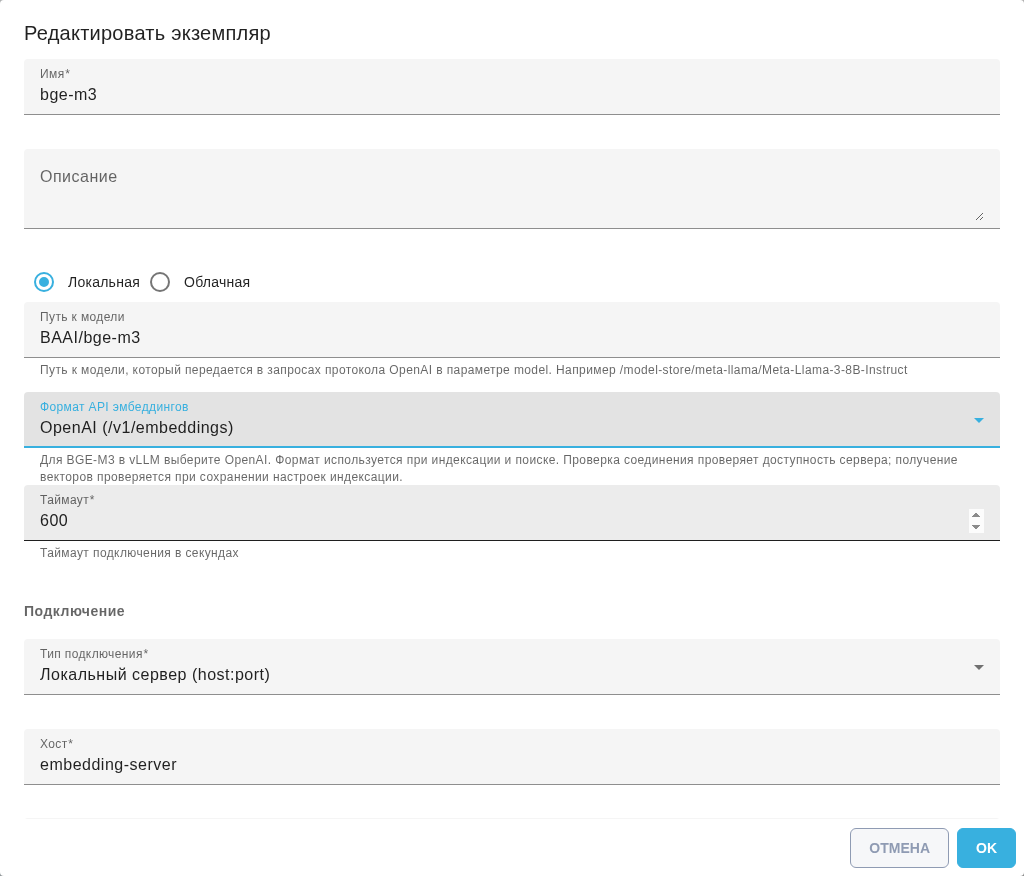
Edit Instance dialog: OpenAI format selected for BGE-M3 (Russian interface).
If “Embeddings API format” is missing, the installed version does not yet support selection through the form. Send GET /api/v1/models/{model_guid}/instances/{instance_guid}, obtain the entire data.connection_params object, add "embed_format": "openai", and send the complete updated object in a PATCH to the same URL as {"connection_params": {…}}. A PATCH replaces the entire object, so every connection and authentication field must be retained. A subsequent GET must confirm the value openai. In a version without this field, do not save the instance through the form: it will remove the setting.
The OpenAI format routes Sherpa requests to /v1/embeddings. The form's connection test checks server availability. Sherpa checks actual vector generation when indexing settings are saved. Then follow the steps below to select the new model and dimension 1024.
Running without the local Embed model#
When an external model, such as one served by vLLM, is selected for indexing, the server administrator can disable local model loading inside aiserver-embed. The container is still required for document processing, OCR, text chunks, BM25, vector storage, and search. EMBED_MODEL_API_BASE_URL must point to this Sherpa service, rather than a standard vLLM server.
- Configure the external model and assign it as the indexing default in its card on Models. Check indexing and search with one test document.
- Set the following in the installation
.envfile:
EMBED_LOCAL_MODEL_ENABLED=false
- Recreate only the Embed container from the installation directory. For the standard
docker-compose.ymlfile:
docker compose up -d --no-deps --force-recreate aiserver-embed
If the installation uses another Compose file or project name, use the same -f and -p parameters used to start it. Recreating the container briefly interrupts document processing and search. After startup, check the test document again. The logs will show Local embedding model disabled by EMBED_LOCAL_MODEL_ENABLED.
With false, the local model is neither loaded nor downloaded, even when its weights already exist. Saved weights remain on disk. EMBED_DOWNLOAD_MODEL=false only prevents downloading missing weights. It does not disable loading a saved model. The local /v1/embeddings and /v2/embed endpoints return HTTP 503 model_not_loaded. Vectors must come from the selected external model.
The default is EMBED_LOCAL_MODEL_ENABLED=true. To restore the local model, set it to true and recreate the container. If weights are missing, downloading them also requires EMBED_DOWNLOAD_MODEL=true.
Change the model#
To switch the indexing model:
On Models, check that the required model supports Indexing and has exactly one available active instance. If no card exists, create the model and instance or contact an administrator.
Select Default in the Indexing row of the new model card. Enter its actual dimension in the Default indexing model dialog. Changing the dimension alone in Document settings does not select another model.
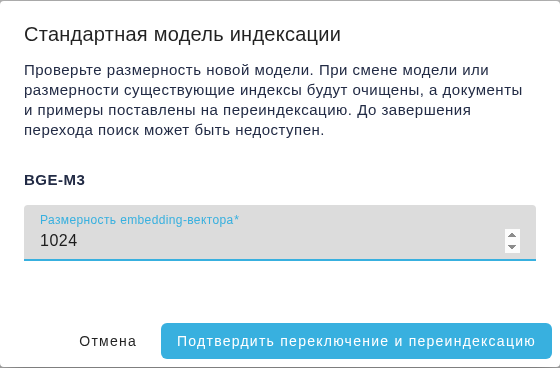
Default indexing model dialog: dimension 1024 for BGE-M3. Russian interface.
Click "Confirm switch and reindexing" to validate and start the transition. The server checks the model, vector dimension and search index. After validation, it saves the model and dimension, clears old vectors and queues automatically indexed documents. Saved text is retained. Only files without saved text require OCR again. Source files are retained. "Delete all vectors and reindex" is not required separately. Switching models also starts a transition when the dimension stays the same.
It is necessary to wait for document processing: Pending → Processing → Ready. For a file with Awaiting manual indexing status, open it and click the "Re-index" button, then wait for Ready. Files with Not indexed status are not indexed. The server reindexes assistant answer samples automatically.
Search for content in a known document and confirm that the required files have reached Ready. If a file shows Error, read and resolve the cause. Then click the "Re-index" button for that file. To process all files again, use Delete all vectors and reindex separately.
A transition status of ready means the settings change has finished; it does not mean every file has reached Ready. If an API response shows queued_files, it counts files placed in the queue, not files already processed. It is necessary to check document statuses and search after indexing finishes.
With no indexing default, Document settings show "Not assigned". Vector operations return 404 model_not_found without using .env settings. Clearing the default in the model card retains files and vectors, but indexing and vector search remain unavailable until a model is assigned. An unavailable active instance returns 503 model_unavailable.
Examples#
- 384 → 1024. Select a new model that returns 1024-dimensional vectors, enter 1024, and click "Confirm switch and reindexing". It is necessary to wait for file reindexing and check search.
- 1024 → 384. Select a model that returns 384-dimensional vectors, enter 384, and follow the same steps.
- 384 → 384, different model. Select a different model, keep 384, and click "Confirm switch and reindexing". Changing the model starts reindexing even though the dimension stays the same.
When text chunking changes#
When "Chunk size" or "Chunk overlap" changes, a warning icon appears beside the field. Hover over it or focus it with the keyboard. Save removes old text chunks and reads files again. Scans require OCR again and may take much longer. If the model or dimension also changes, new vectors are created after the files are read.
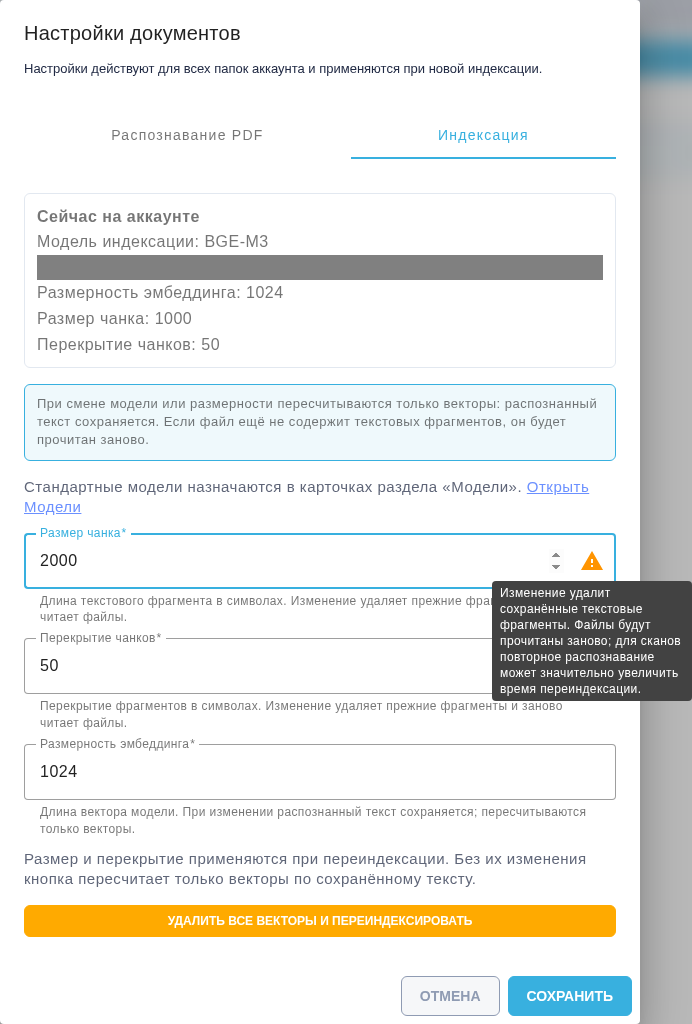
Documents settings dialog, Indexing tab: chunk size warning. Russian interface.
With unchanged chunk size and overlap, Delete all vectors and reindex recalculates only vectors from saved text. There is no separate command to repeat OCR for every file. Files without saved chunks are read again.
If the change is rejected or interrupted#
If the preliminary check fails because the model is unavailable, the dimension is wrong, or the index is not prepared, the cause must be resolved and the settings saved again. If a simultaneous chunk size or overlap change is rejected because of API-only chunks, their text and metadata must be saved outside the system, those chunks or their file removed, and the operation retried. Model-only and dimension-only changes preserve API chunks.
The "Resume transition" button, locked controls and remaining-work counters are available starting with version 2.5.4. In version 2.5.3, the "Save" button resumes the transition.
On a production server, transition retries, reindexing and data deletion must be agreed with the responsible administrator in advance.
An incomplete transition requires the following steps and the documents:update and ai_models:read permissions.
- Close the settings dialog, then select "Document processing" on the Documents screen and open the "Indexing" tab.
- Keep the model, dimension, chunk size and overlap loaded from the server. These are the values of the started transition. They may differ from those before the first attempt. The new interface locks these fields and recognition settings. "Currently on this account" shows the saved configuration. The counters show remaining files and assistant response samples. They refresh after reopening the dialog or an error.
- After resolving the displayed error cause, select "Resume transition". In version 2.5.3, select "Save" without changing any of the four parameters. The server continues the remaining work. If the retry fails, provide the administrator with the error time and file identifier.
- After the transition finishes, wait until the required documents have the "Ready" status and check search using a known passage. The
readystate confirms the settings transition, not completion of every file. Send the Chat request again after search is restored. - Save any new chunk size and overlap separately after the transition finishes.
Example: an account has started a transition with BGE-embed, dimension 1024, chunk size 4000 and overlap 200. To finish it, select "Resume transition" on the "Indexing" tab of "Document settings". These values remain unchanged. Save the new values 1000 and 50 separately after completion.
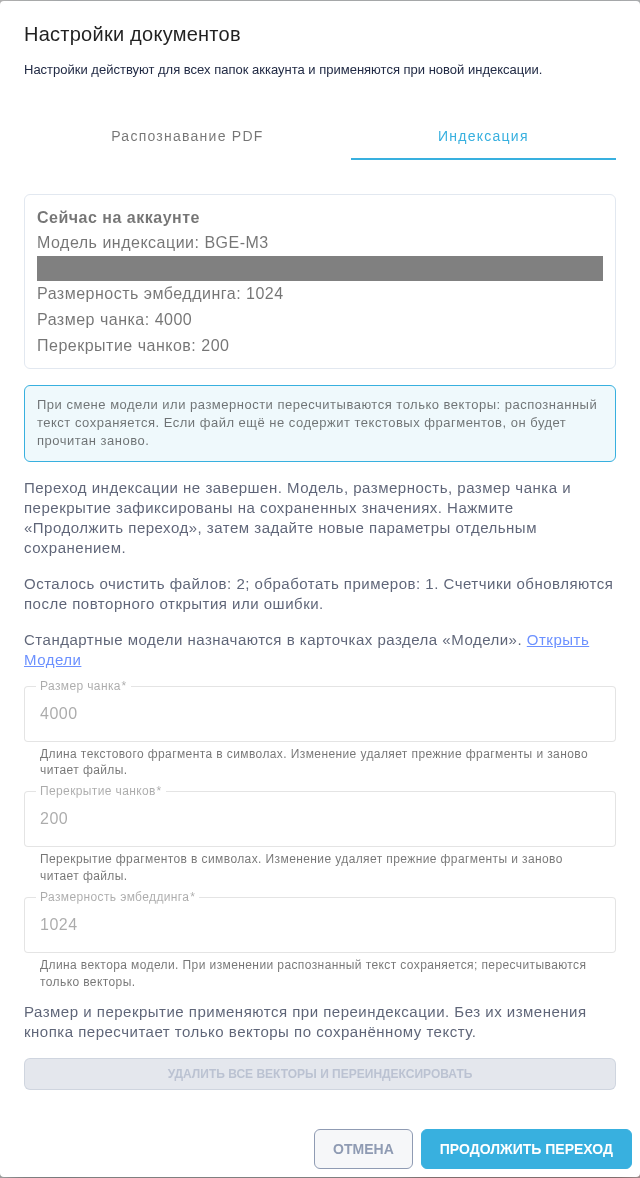
"Indexing" tab in "Document settings". Russian interface.
The new interface saves recognition and indexing separately. To change both groups, first save recognition without changing indexing. Reopen the dialog and save indexing next. Recognition cannot be changed during an incomplete transition. Resuming does not rewrite OCR or the default recognition model. If an OCR save is partial, the dialog reloads the stored values. Check them before retrying. Check the default recognition model on the Models screen. In version 2.5.3, OCR settings may have been saved separately after an error.
Starting with version 2.5.4, a retry skips completed files and response samples. If restoring saved chunks of a manually indexed file fails, the file remains unfinished until a successful retry. Original files are preserved. Do not delete them or manually clear pending merely to restore search.
Administrators must distinguish a wait timeout, server error response, unavailable connection and database error. The update has a separate vector deletion timeout: EMBED_CLEANUP_TIMEOUT_SECONDS, default 120 seconds, accepting integers from 1 to 3600. Invalid values use the default. This setting does not change model request timeouts. A proxy can terminate the overall request earlier. After resolving the cause, retry with the same configuration. The embedding server may finish deletion after a timeout, so the error alone does not prove that data remained unchanged.
Check the model path and error cause#
To check the connection, the selected indexing model’s single active instance must be opened on the Models screen. The "Model path" field must contain the embedding server’s identifier, for example BAAI/bge-m3. A cloud instance can use the connection parameter model. When both values are set, "Model path" takes precedence. The identifier can be checked through the selected server’s /v1/models. An empty field must not be used to select the chat model.
An empty path is rejected before contacting the server. "Open Models" in Document settings opens the cards where the default assignment and instance parameters are configured. If the server rejects the identifier or returns a different dimension, the message identifies the selected model and parameters to check.
Example: cleanup of "document.pdf" stopped because the embedding server was unavailable. The message shows the file name and cause. The administrator must restore the connection and resume the transition with the saved parameters. Starting with version 2.5.4, files already completed are not cleaned again.
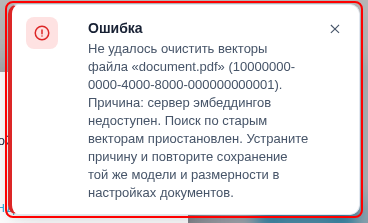
Vector cleanup error. The interface is in Russian.
If Chat cannot search documents#
The Chat request is saved when a known search conflict occurs. An explanation of an incomplete transition, mismatched dimension or search vector model appears instead of a model answer. The reply can also explain that the indexing model could not create a search vector. It names the model and dimension from the settings. Reloading the page does not automatically run the refused request.
- An administrator must check the "Indexing" tab in "Document settings". If cleanup is incomplete, resolve the displayed cause and resume with the same model, dimension, chunk size and overlap.
- After the transition finishes, wait for the required documents to be ready and check search against a known text fragment. The
readystate does not confirm that all files are ready. - After indexing is restored, the user must send the request in Chat again. For a dimension or vector source mismatch, check the selected model and reindex the documents. If the model is unavailable, check its active instance’s connection and model path.
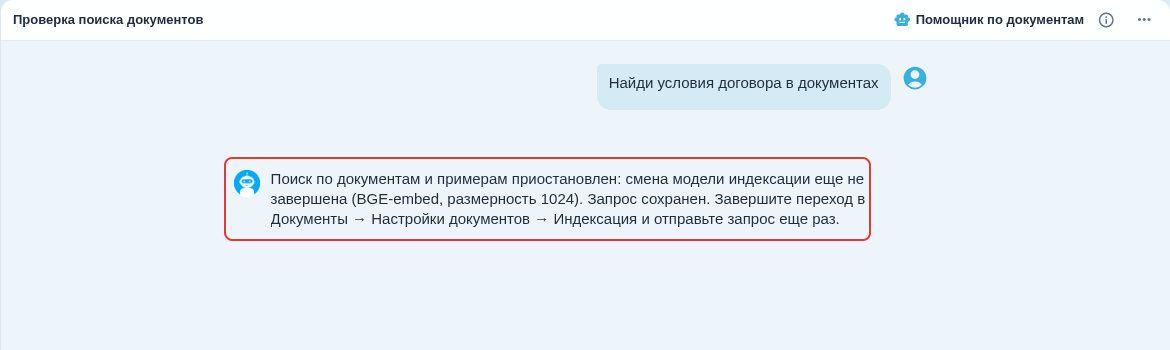
Chat explanation of an incomplete indexing transition. Russian interface.
For administrators: another dimension#
For a dimension other than 384 or 1024, prepare the index for the account after the version 2.5.1 migrations and before saving the new model. The full SQL, checks, and commands for the standard client installation are in the "Additional dimensions after the upgrade" section of the index preparation guide. Copy the SQL from there to a local file and specify the numeric account ID and actual model dimension. After the command succeeds, confirm the transition in the model card with "Confirm switch and reindexing".